Public leaderboards tell you how a model does on puzzles. They don't tell you whether it will read a lender's disclosure word for word, remember what a caller said two turns ago, or call the right tool with the right date.
Cresta-Bench is our internal benchmark: four purpose-built AI agents and 181 test cases, designed to reflect the production-grade challenges we've seen in real-world contact center deployments.
In our latest run of fourteen models, the best model passed 89.5% of test runs, and most of the gap between models came from following the agent's own instructions: taking the right action, in the right order, and applying the written exception instead of the general rule.
Why We Built Our Own Benchmark
A Cresta AI Agent is not a model in isolation. It is a model inside a harness of prompts, tools, knowledge bases, guardrails and platform code, talking to a real caller, often in a regulated industry. Whether a new model makes that agent better depends on how well it orchestrates all of these parts at once, and public leaderboards don't measure that.
Cresta's AI/ML team built Cresta-Bench to answer the question our customers ask: which model should power this agent?
Three principles shaped the design:
- The unit under test is the whole agent. "Model A beats model B" means A beats B inside the same fixed agent, with the same prompts, tools and knowledge. We never score a raw LLM.
- Test cases reflect the kinds of workflows contact centers run across different industries, such as lending, health plan provider lines, callback scheduling and airline support, so the problems in the benchmark are the ones we see in real deployments.
- Every result should support a decision: pick this model, ship this agent, or fix this part of the agent first.
Public agent benchmarks usually run in synthetic domains, with short, tidy policies written for the benchmark. Production prompts look different; they are long, they carry exceptions for specific states, products and customer types, their tools define parameters with strict meanings, and their callers give partial answers, change their minds or ask two things at once.
Several of the failure patterns in our results, such as applying a general rule where the prompt wrote an exception, or skipping an intake question that only the prompt requires, appear only when the prompt has production-level complexity. Because Cresta-Bench's agents are designed to match that complexity, a model's score reflects the kind of work it would do in a real deployment.
Building Safe, Realistic Benchmark Agents
Each benchmark agent is a self-contained AI agent modeled on a common customer experience workflow, with the long prompts, strict tool contracts and product- and state-specific exceptions that production agents carry. Two rules shape every agent:
- No customer data, no customer identity: Benchmark agents contain no customer data or brand identity. Names, phone numbers, accounts and addresses are synthetic.
- Backends are mock-only by construction: CRM lookups, scheduling and telephony transfers return versioned fixtures. The agent package contains no production clients, credentials or dialable numbers, and each agent's test suite runs end to end with network access denied.
Table 1 lists the four benchmark agents, each built around a different customer experience workflow:
How a Test Run Works
Each test case describes a simulated caller (the visitor) with a goal, a persona and the details they will share, plus the checks the agent must pass.
Keeping the simulated caller honest
The visitor is itself an LLM, and simulated callers drift: they invent an account number, volunteer a detail they were told to withhold, give up on a demand they were told to repeat, or start talking like the agent. When that happens, the run no longer tests what the case was written to test. So each caller prompt is written as a contract: who the caller is, what they want and in what order (with exact lines to say), the only facts they have, and hard rules such as never inventing a figure, name or date, and never hanging up. We avoid generic caller prompts, which tell the caller to make up details and mix them up, building failures in by design.
Every run is checked against that contract
A rule-based pre-check flags obvious slips, such as a number that appears nowhere in the script or a caller who offers help like an agent. An LLM judge then reads the caller's script, the case description and the transcript, and answers one question: did the caller follow its own instructions? It records the breach type (early reveal, invented fact, forgotten fact, goal shift, over-cooperation) and whether the situation the case measures still happened. The agent's performance must not move that verdict: an agent that faced the situation and failed it has failed.
A caller breach never flips a verdict
A run is excluded only when the caller never set up the scenario or broke it; runs where the caller slipped but the tested situation still happened stay in and are listed for review. In the October run, 212 of 7,602 scheduled runs (about 3%) were excluded; 75 of them had passed, so exclusion took away passes as well as failures.
Keeping the test cases honest
A low score should mean the model made a mistake, not that the test did. So every check traces to something the agent was actually told: a line in the prompt, a tool description, a tool result or a knowledge base article. An LLM judge whose situation never came up in the conversation records "not applicable" rather than a pass or a fail. After each run we audit the cases that most models fail. For each failure, we ask what caused it: the model, the caller script, the check itself, or two parts of the agent that contradict each other. In our latest audit of the lowest-scoring cases:
- Most were valid: the models really were breaking a rule the agent states;
- One was broken by its caller script and was removed from scoring;
- One was decided by a single check that graded something the agent's tool already handled, and that check was dropped.
The visitor talks to the benchmark agent through the same runtime that serves production, and tool calls go to mocks. Every case runs three times per model, because the same model can pass a case once and fail it the next time.
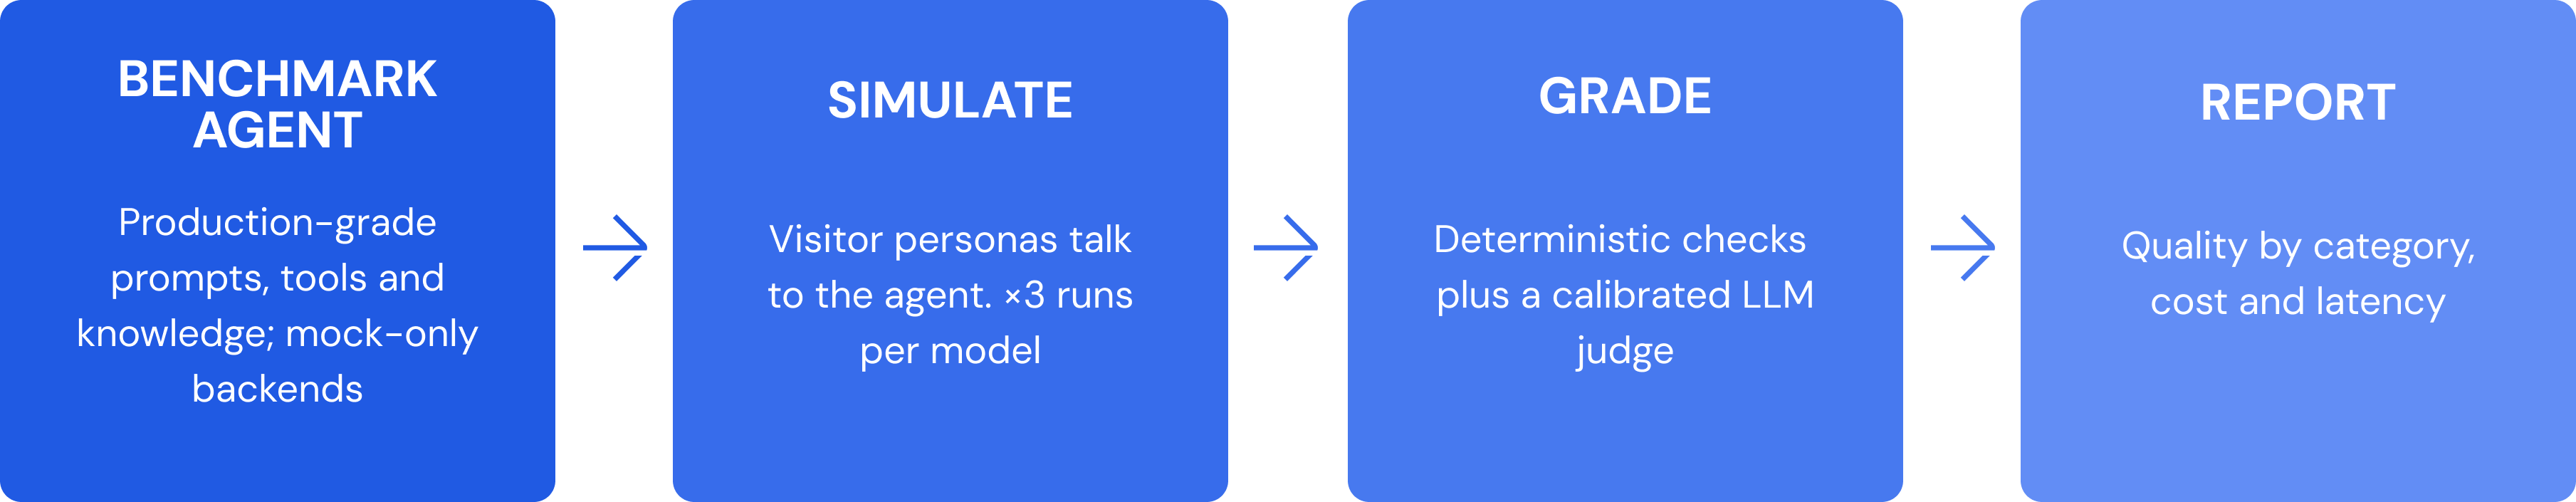
When the evidence is structured, such as which tool was called with which arguments, a deterministic check renders the verdict. Where judgment is needed, such as whether a reply answered the question, an LLM judge grades the transcript against a yes-or-no rubric, calibrated against human labels. We report two headline metrics, each averaged across the four agents so every agent counts equally:
- pass@1, the share of individual runs that pass all of a case's checks.
- pass^3, the probability that a case passes three runs in a row. At thousands of calls a day, consistency matters as much as the average.
A Taxonomy Built on What the Agent Had to Agree With
A pass rate tells you how good an agent is, not what to fix. We compared four ways to categorize failures: by capability area, by conformance target, by stressor, and by stack layer.
Capability areas were hard to label consistently: the same failure could reasonably be filed as a memory, reasoning or tool-use problem, so different reviewers would label it differently; stressors and stack layers worked better as extra fields on each case than as categories.
We adopted the conformance-target taxonomy, whose labeling rule is mechanical: ask which single artifact could have made the opposite behavior correct, open it, and check. Each category points to a different reference, and so to a different owner for the fix.
Instruction conformance is the largest category, so we break it into its three main aspects when reporting: action selection (taking the right action or tool call), ordering (doing required steps in sequence) and precedence (following the winning instruction when two compete, such as a general rule and a written exception to it). Runs are text-in and text-out, so speech recognition errors and turn-taking are out of scope, and the taxonomy also leaves out retrieval quality so it doesn't blur the scores.
Results: 14 Models, 4 Agents
Our October 2026 run compared fourteen models on all 181 cases, three runs each, inside the same benchmark agents. Every model ran at the lowest reasoning setting we could run cleanly: on a voice call the caller hears every pause, and long reasoning adds seconds to a reply. Table 3, in the next section, lists every model's reasoning setting and pass rates alongside its cost and latency. Below are some overall trends we observed from the run:
The top models win on judgment calls
Claude Opus 5.5 led at 89.5% pass@1 and 82.6% pass^3, followed by Claude Sonnet 5.5, Gemini 3.8 Flash and GPT-6 Sol (84–88%). On the most scripted agent, the senior-health callback line, Claude Opus 5.5, GPT-6 Sol and Claude Sonnet 5.5 were nearly level at 93–96%, and even GPT-5.4, fifth overall, kept pace. The gaps opened where the prompt leaves decisions to the model. For the lending agent, Opus and Gemini 3.8 Flash reached 81%, against 68% for GPT-6 Sol. Among OpenAI models, GPT-6 Sol beat GPT-5.4 on three of four agents, by 35 points on airline support, at about the same cost ($0.113 vs $0.110). That's a third of Opus's cost.
The gap is in following instructions, especially order and exceptions
Instruction conformance tracks the overall ranking almost exactly, more closely than any other category. It also holds about three quarters of all checks, so it accounts for a similar share of the extra failed checks in the weaker models, most of them wrong or missing actions.
Within it, two skills split the field most sharply. The first is ordering: doing required steps in the stated sequence. It ranged from 99% for Claude Sonnet 5.5 to 71% for GPT-5.6 Luna. The second is precedence: following the winning instruction when two models compete. The top five models got it right 96–99% of the time, while Qwen 3.8 Max, Gemini 3.6 Flash, both Luna models and DeepSeek fell to 74–78%, often applying the general rule where the prompt had written an exception. Enterprise prompts are full of exceptions and required sequences, so these are the first skills we check.
Smaller models can work, for the right agent
Below the top four, which model is best depends heavily on the agent. GLM-5.3 placed fifth on airline support (80%), ahead of GPT-5.4, but scored 54% on lending; GPT-5.4 itself ranged from 95% on the callback line to 52% on airline support. GPT-5.6 Luna scored 65% on airline support at about a cent per conversation, yet 21% on the callback line.
Smaller models also tend to cut corners the same way: the Luna models skipped intake questions that only the prompt required, and Gemini 3.6 Flash sometimes miscalculated relative dates. Consistency is a further gap: Kimi K3 passed 59% of runs but only 35% of cases three times in a row. A cheap model can be the right choice, but only after it's tested on the type of agent it will run.
Finally, a few test cases scored very low across models. When we traced them, the cause was sometimes the agent's design and sometimes the case or a check, not the model. Separating 'pick a better model' problems from 'fix the agent or the test' problems is one of the most useful things the benchmark does.
Putting it together: quality, cost and latency
A model that scores two points higher but responds noticeably slower can make a voice agent worse. So we also track cost per conversation and the time to first token (TTFT), which sets how long a caller waits for each reply on a voice call, measured separately for tool-call turns, where the agent must call a tool before answering, and no-tool turns. We also track agent time per conversation: the total time the agent spends producing its replies, including every model call and tool call.
These numbers come from test runs and depend on our infrastructure and serving configuration at the time, so they are for comparing models with each other, not production figures. We are calibrating them run over run and will correct them as we go. Even so, the pattern is useful: GPT-6 Sol comes within about 5 points of Claude Opus 5.5 (84.3% vs 89.5%) at a third of the cost ($0.113 vs $0.341 per conversation), and Gemini 3.6 Flash scores about the same as Qwen 3.8 Max and GLM-5.3 (about 66%) at half Qwen 3.8 Max’s cost ($0.047 vs $0.094).
Judging the judge
A benchmark graded by an LLM is only as reliable as its judge. We replayed more than 10,000 judge calls across eight candidate judge models, on 50 human-labeled checks (each replayed five times) and a larger sample from a full run, measuring agreement with humans, self-consistency and cost. Nearly every disagreement with the humans traced to three rubrics with undefined decision boundaries, which each model resolved in its own consistent way. Once we defined those boundaries, six of the eight models matched the human labels on all 250 graded calls and the other two missed one each.
With accuracy settled, cost decided it: every model was at least 99.2% self-consistent, yet the bill to judge one benchmark run ranged from $0.41 to $35. We adopted GPT-6 Luna as the default judge, 65 times cheaper than our previous judge at equal accuracy. In a live check on the suites a second tuning round covered, it split 0.10% of checks (gave different verdicts on repeated calls), against 0.23% for the previous judge; on suites that round did not cover, it still split more failing checks than the previous judge, so rubric tuning continues. Judges run offline with medium reasoning, since no caller is waiting on them.
Lesson learned: When an LLM judge disagrees with human labels, look at the rubric before you look at the model.
What's next
- More models. We will add more Claude and Gemini models (e.g. Gemini 4 Argon), Muse and leading open-source models.
- Calibrated efficiency numbers. Cost and latency depend on our infrastructure, and we will keep calibrating them to stay as close to production as possible.
- More agents and industries, including outbound sales workflows and harder long, multi-turn cases, plus stress tests reported alongside the main scores.
When we recommend a model for Cresta AI Agent, that recommendation rests on evidence from workflows like the ones our customers run, measured on quality, consistency, cost and speed together.
We have published these results on Fireworks’ Specialized Intelligence Index (SII): chart, tabular breakdown, methodology. If you are interested in working on cutting edge AI research, come build with us!