7 steps to monitor call quality successfully in 2027

- Scorecards fail when they reflect what leaders assume matters, so build them on the behaviors that conversation data shows drive outcomes
- Sampling leaves most calls unchecked for required disclosures, so coverage is a compliance issue, not just a coaching one
- The strongest programs pair AI scoring on every conversation with human reviewers who handle calibration, edge cases, appeals, and coaching
- Regular calibration keeps human and AI scoring consistent, so agents get the same rating for the same behavior
- Coaching built on every conversation feels fairer to agents and is more likely to change how they handle calls
Many contact centers still judge agent performance from a small sample of reviewed calls.
There's a strong push to change that.
In a recent Gartner survey, 91% of service and support leaders said executive leadership is pressing them to implement AI. And automating call analysis at scale is a top AI use case.
But automation alone won't fix your call quality program. We’ll break down the steps you need to take and the consequences of skipping them.
To start, let’s align on what call quality monitoring is and why it’s increasingly important.
What is call quality monitoring?
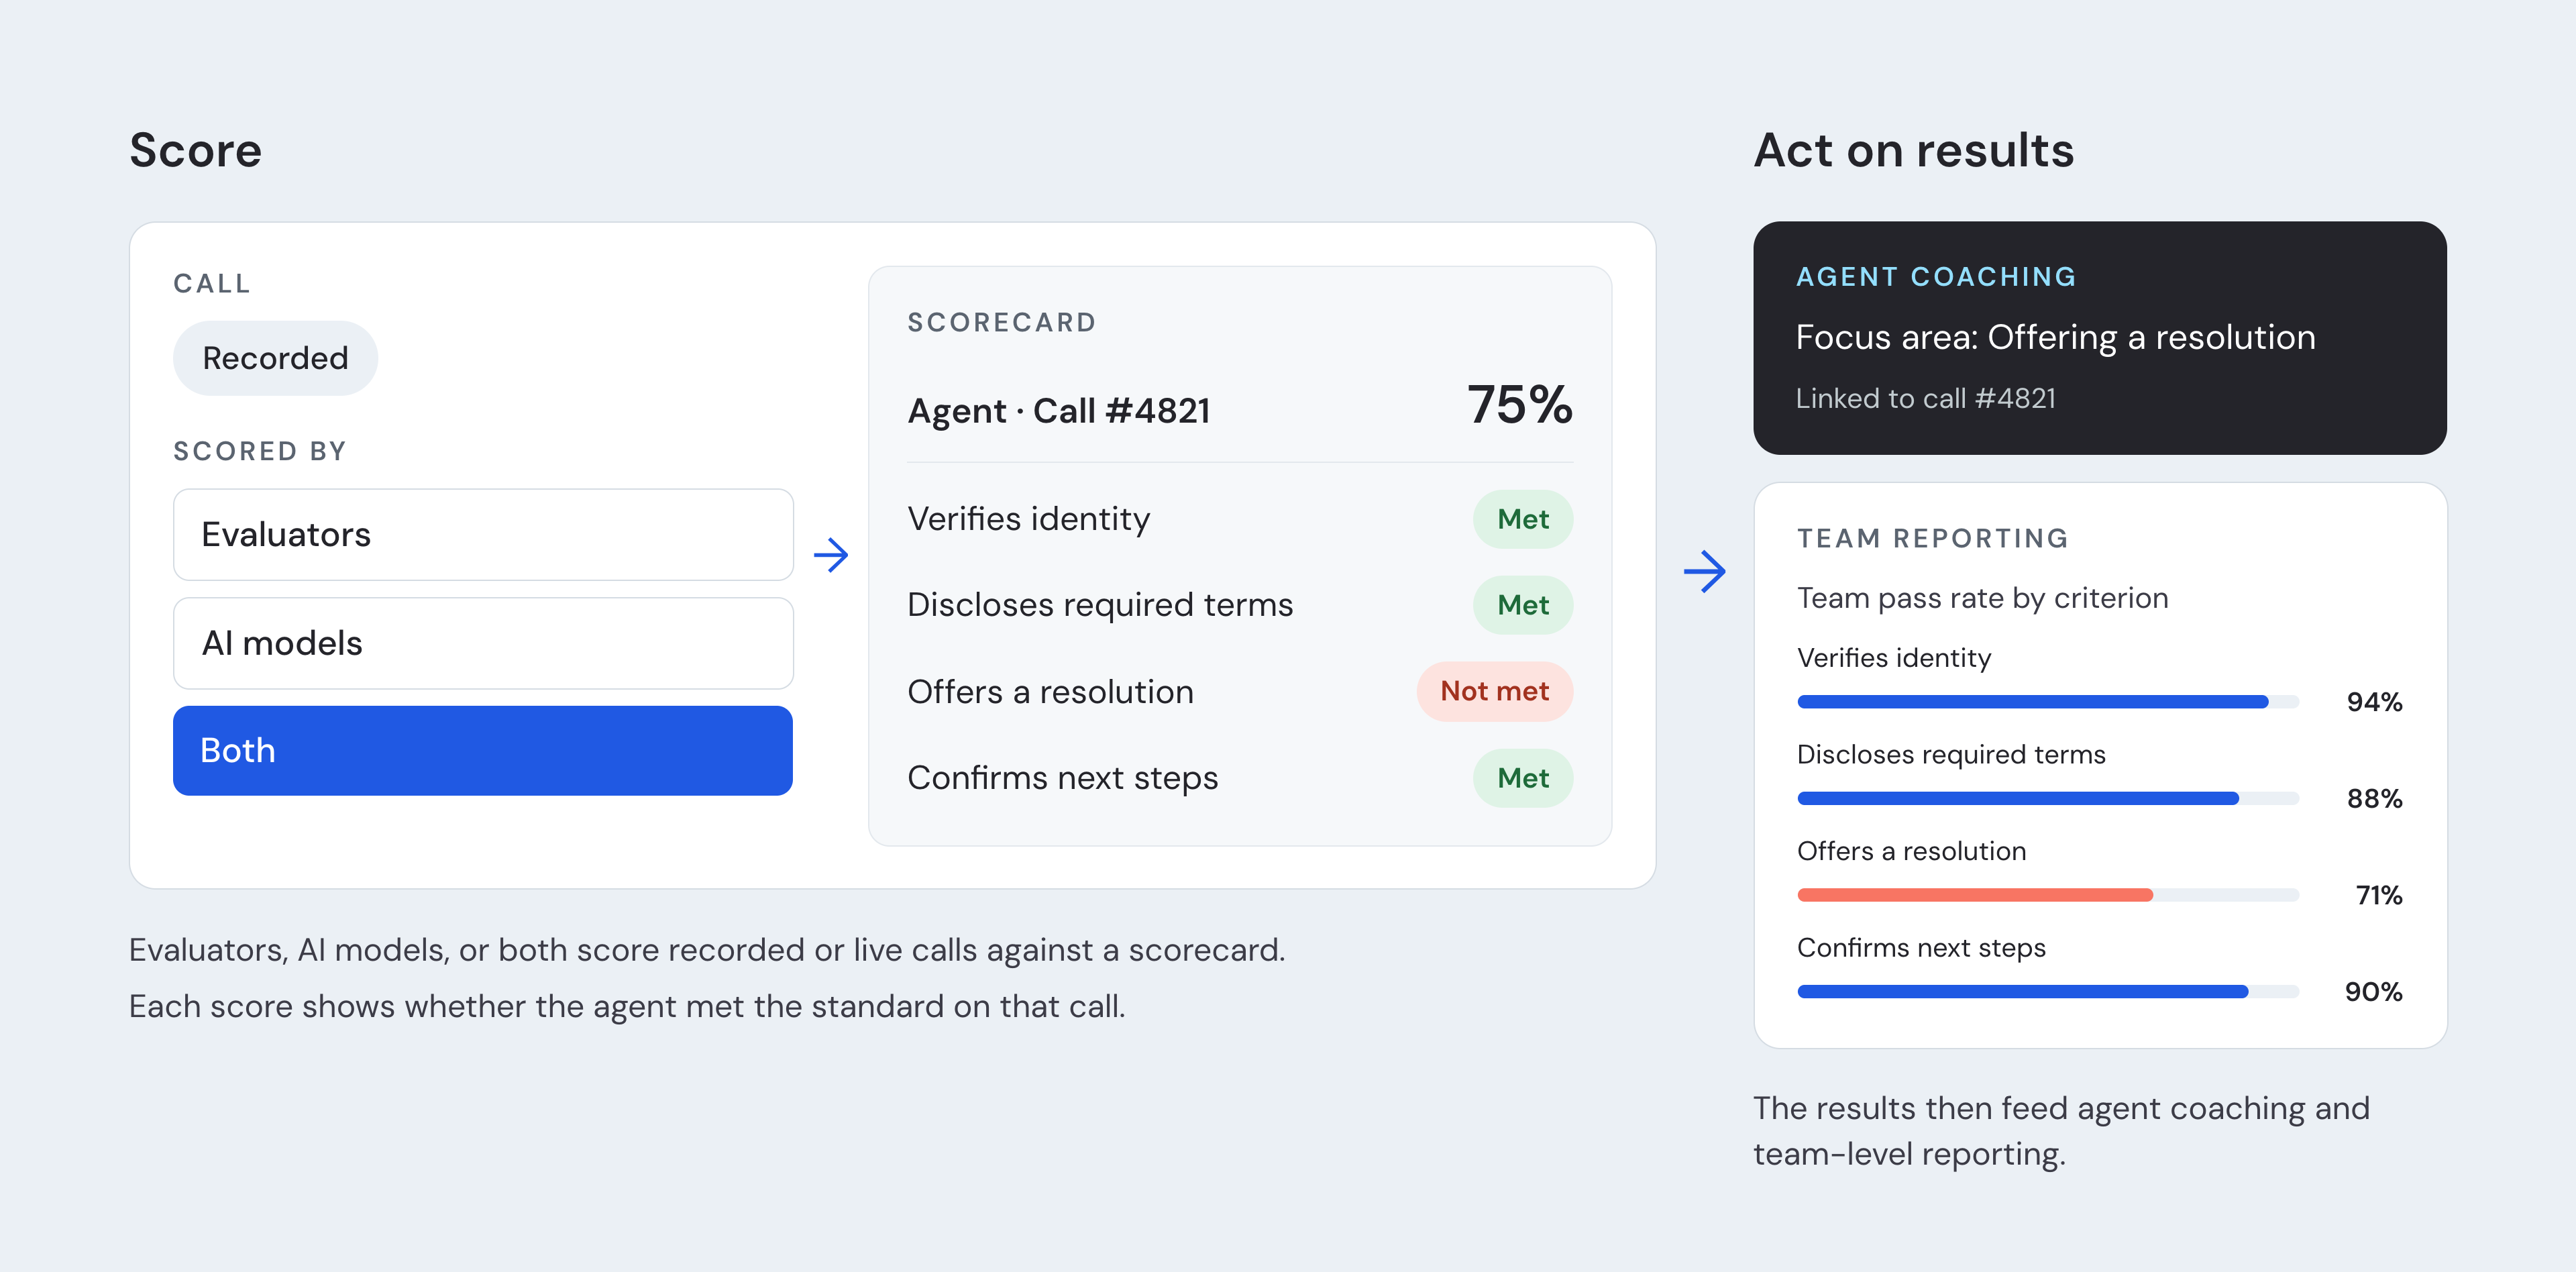
It's the practice of reviewing customer calls against a defined standard to measure agent performance, compliance, and customer outcomes, and then using what you find to coach agents and fix processes.
Evaluators, AI models, or both score recorded or live calls against a scorecard. Each score shows whether the agent met the standard on that call. The results then feed agent coaching and team-level reporting.
Most programs share four core capabilities:
- Call recording and transcription, so every conversation can be reviewed
- Scorecard-based evaluation against weighted and pass/fail criteria
- Compliance checks for required steps and disclosures
- Coaching and reporting workflows that turn scores into action
Related: AI quality management explained
Why call quality monitoring matters
AI is taking the simple contacts, and what’s left for people is harder. Case in point: In our 2026 CX workforce report, 93% of 300 CX leaders said human-handled calls are getting more complex.
That makes every remaining human conversation higher stakes for compliance, retention, and satisfaction.
Most quality programs weren’t built for that.
Manual QA typically reviews a small percent of interactions, so coaching and compliance decisions rest on a thin slice of calls.
This leaves you vulnerable in several ways:
- Sampling leaves most calls unreviewed for required disclosures. A compliance miss can sit outside the sample, and depending on the issue, it can lead to regulatory penalties or legal exposure if it isn’t caught and addressed
- Coaching built on a few calls feels arbitrary to agents. One randomly chosen call may not be representative, which makes QM feel punitive
- Feedback arrives too late to change behavior. By the time a call is pulled, scored, and discussed, weeks have passed and the agent can’t recall the moment
- Strong performers go unseen. Top agents are often reviewed less than struggling ones, so the best behaviors never get recognized or shared
- Leaders can’t see which behaviors drive results. Scorecards reflect assumptions, and a sample can’t show what your top performers do differently
The answer is to analyze 100% of your conversations and take a thoughtful approach as you review and action the insights.
How to monitor call quality effectively
Let’s go through each step you’ll need to take.
1. Identify what "good" looks like
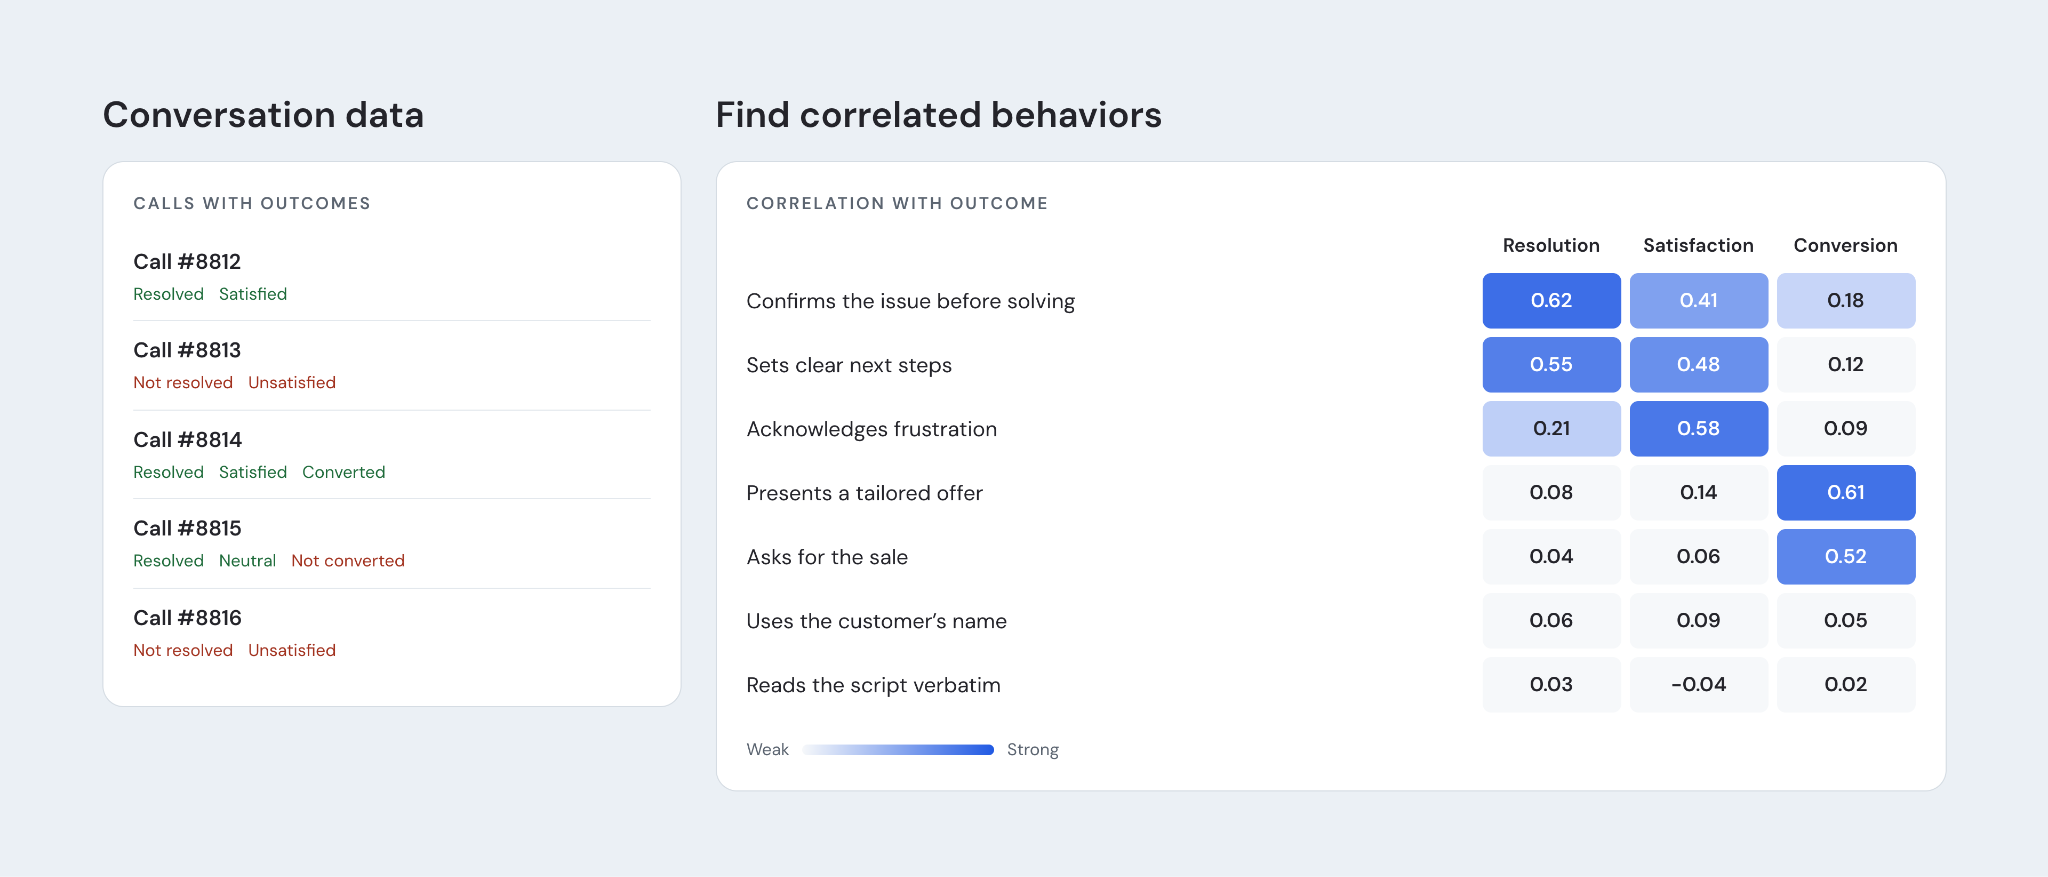
Scorecards have traditionally been wishlists of behaviors executives thought mattered, with no evidence they drove results.
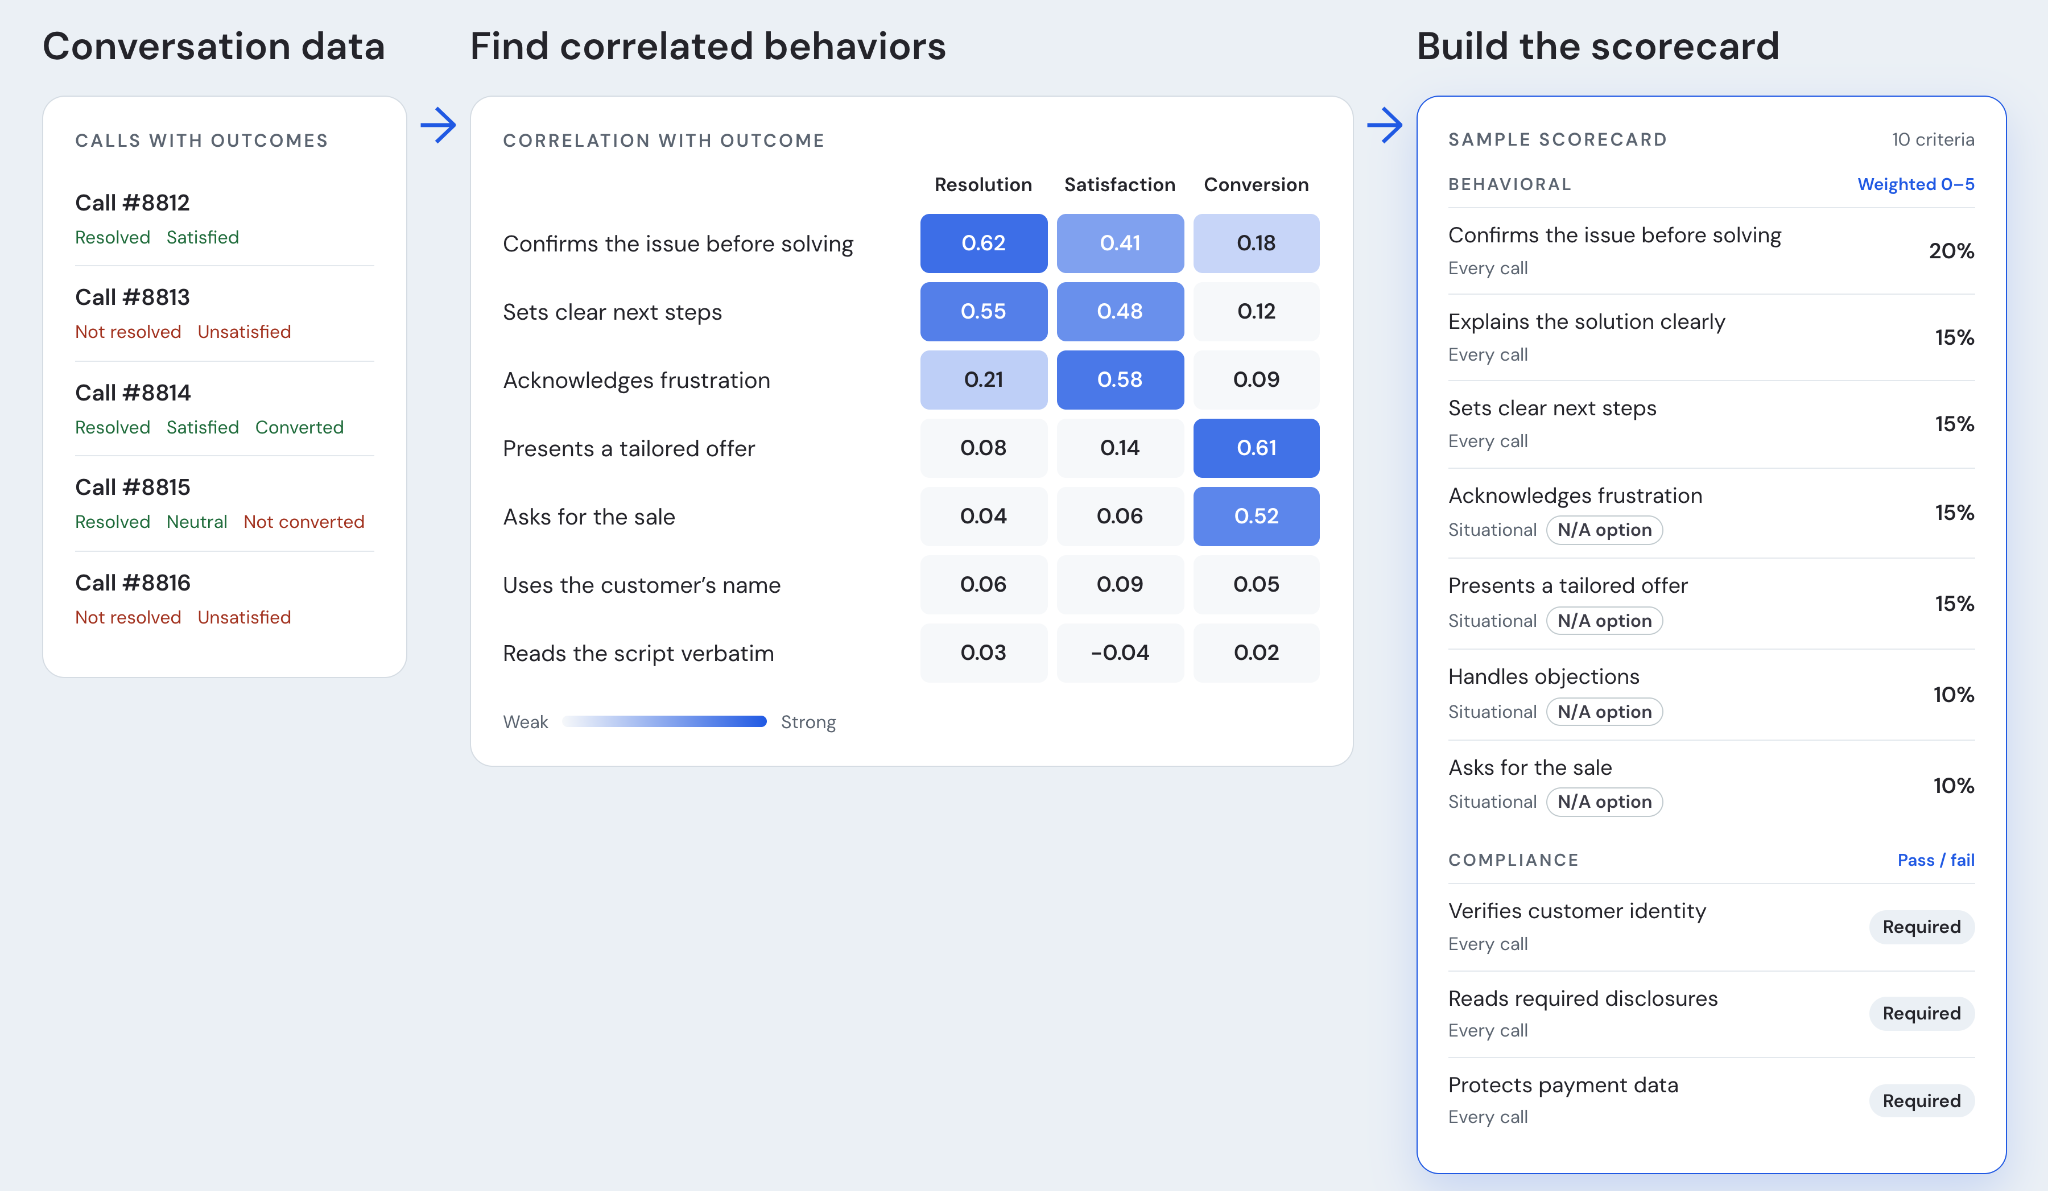
The best approach is to use conversation data to identify behaviors that statistically correlate with resolution, satisfaction, or conversion.
Fortunately, some platforms—including Cresta—can now classify, directly from conversation transcripts, whether a sale was made, whether a conversation was resolved, and what the customer satisfaction score was. That includes predictive CSAT scoring instead of post-call surveys or CRM data entry.
2. Design your quality scorecards
Once you know what good looks like, turn it into criteria on your scorecard.
The biggest mistake in scorecard design is measuring too many things. Overloaded scorecards confuse priorities and slow down evaluations.
Even when AI auto-scores most criteria, too many items create more analysis work on the back end, because leaders have to separate signal from noise.
Instead, focus on the top signals that drive results (from step 1).
You’ll also need to choose your scoring scale.
Weighted 0-5 scales offer flexibility but introduce subjectivity that needs careful calibration, whether the evaluator is a human analyst or an AI model. And binary pass/fail scoring reduces subjectivity and works best for non-negotiable compliance items.
A strong scorecard uses a hybrid: weighted scales for behavioral categories, binary scoring for compliance items, and 8-12 evaluation criteria in total.
The scorecard needs to also distinguish between behaviors that occur on every call and situational behaviors.
For example, authentication happens on every interaction, while objection handling only matters when customers raise objections. As a result, the scorecard needs a "not applicable" option for calls where that behavior never had a chance to occur.
Here's how those choices can look.
3. Adopt a human plus AI approach to monitoring calls
AI systems can automatically score all conversations against your defined scorecard criteria.
Your supervisors or QM teams should then manually review a small set of conversations per agent each month for validation, AI rubric calibration, agent development, and dispute resolution.
This model lets AI take over the repetitive and tedious work, which frees your supervisors to calibrate scores, handle complex cases, and coach agents on specific behaviors.
It also lowers cost. For example, in banking customer care, McKinsey estimates a 20 to 30 percent reduction in quality assurance costs when automated monitoring of every transcript replaces manual reviews.
Related: Contact center compliance regulations and best practices
4. Calibrate evaluators and AI scoring
If you take a humans plus AI approach, use calibration to keep human and AI scores consistent.
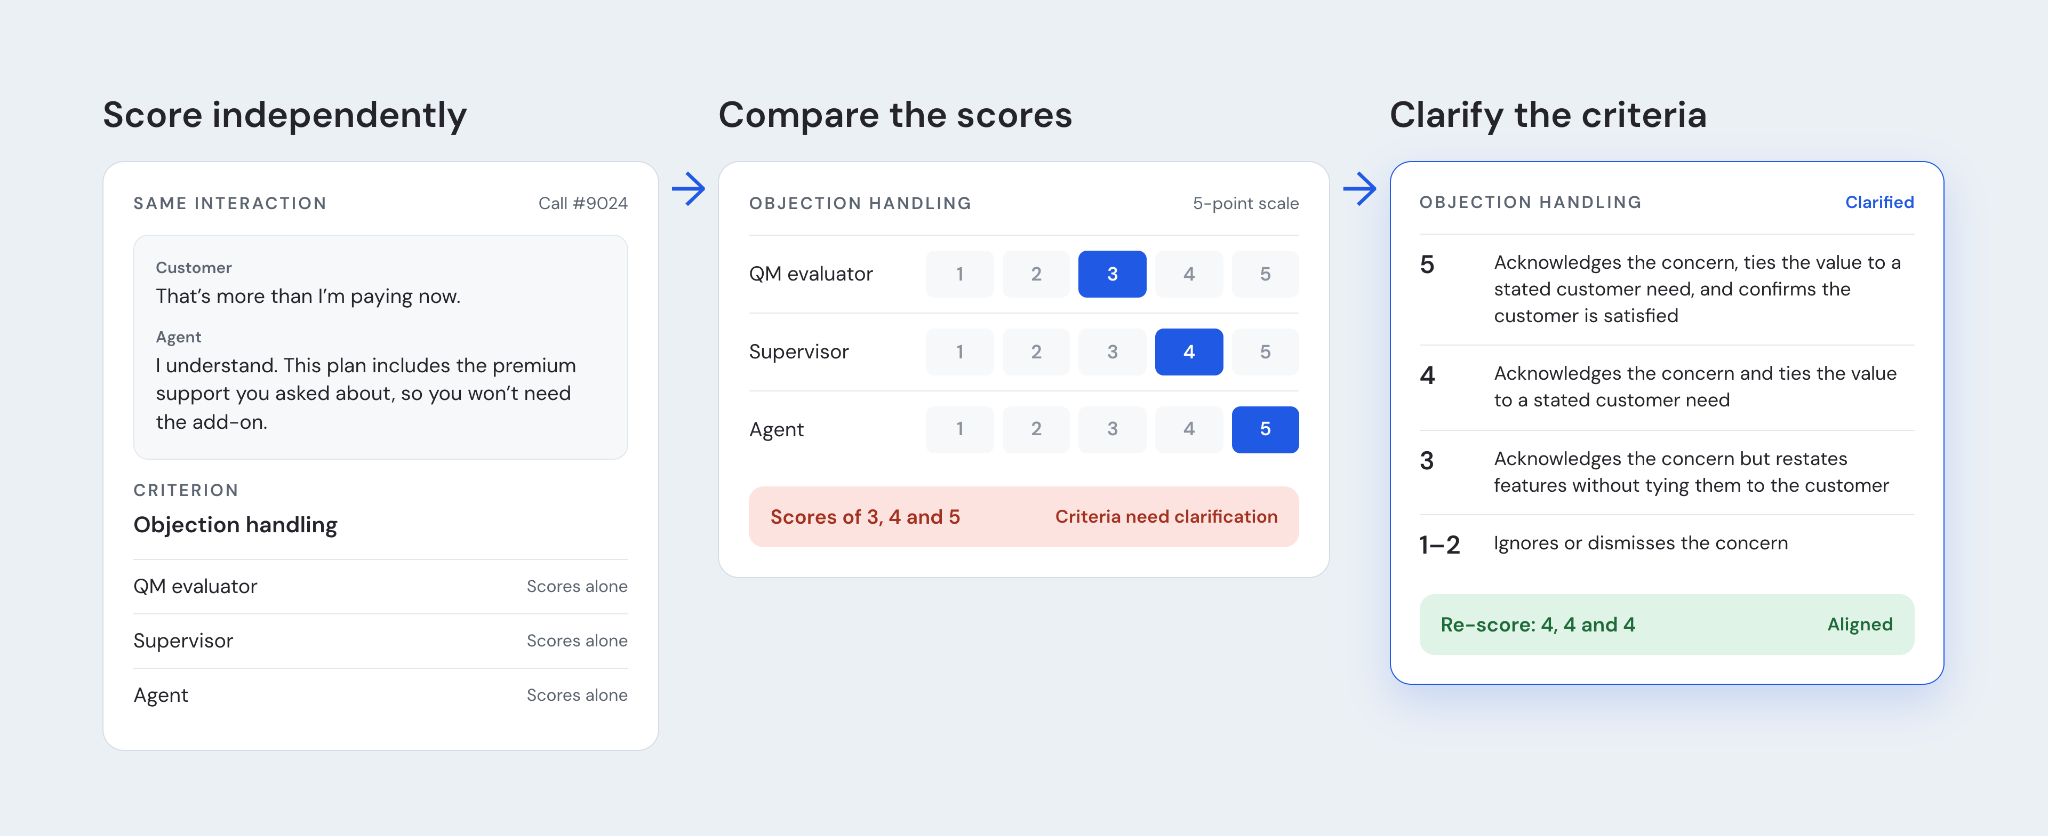
Start by aligning your human evaluators in a calibration session by having QM evaluators, supervisors, and agents each score the same interaction independently.
Then talk through the differences if they exist. When three evaluators rate the same objection handling attempt a 3, 4, and 5 on a 5-point scale, for example, the criteria need clarification.
Then audit the AI against them.
On a regular schedule, have both AI and human evaluators score identical interactions. When the AI consistently rates differently, investigate whether humans are applying inconsistent standards or the model needs retraining.
You can also track how often analysts override AI scores on specific criteria. A frequently overridden rule is an early signal the criteria need refinement before you reach a formal calibration session.
Related: What to fix before you add AI scoring
5. Turn QM results into coaching
Quality monitoring only drives value when evaluation data becomes coaching that changes agent behavior.
Say Sarah, one of your agents, converts fewer sales than her peers. Her QM scorecards show she rarely asks discovery questions when customers raise a price objection, and across your team, asking them correlates strongly with conversion.
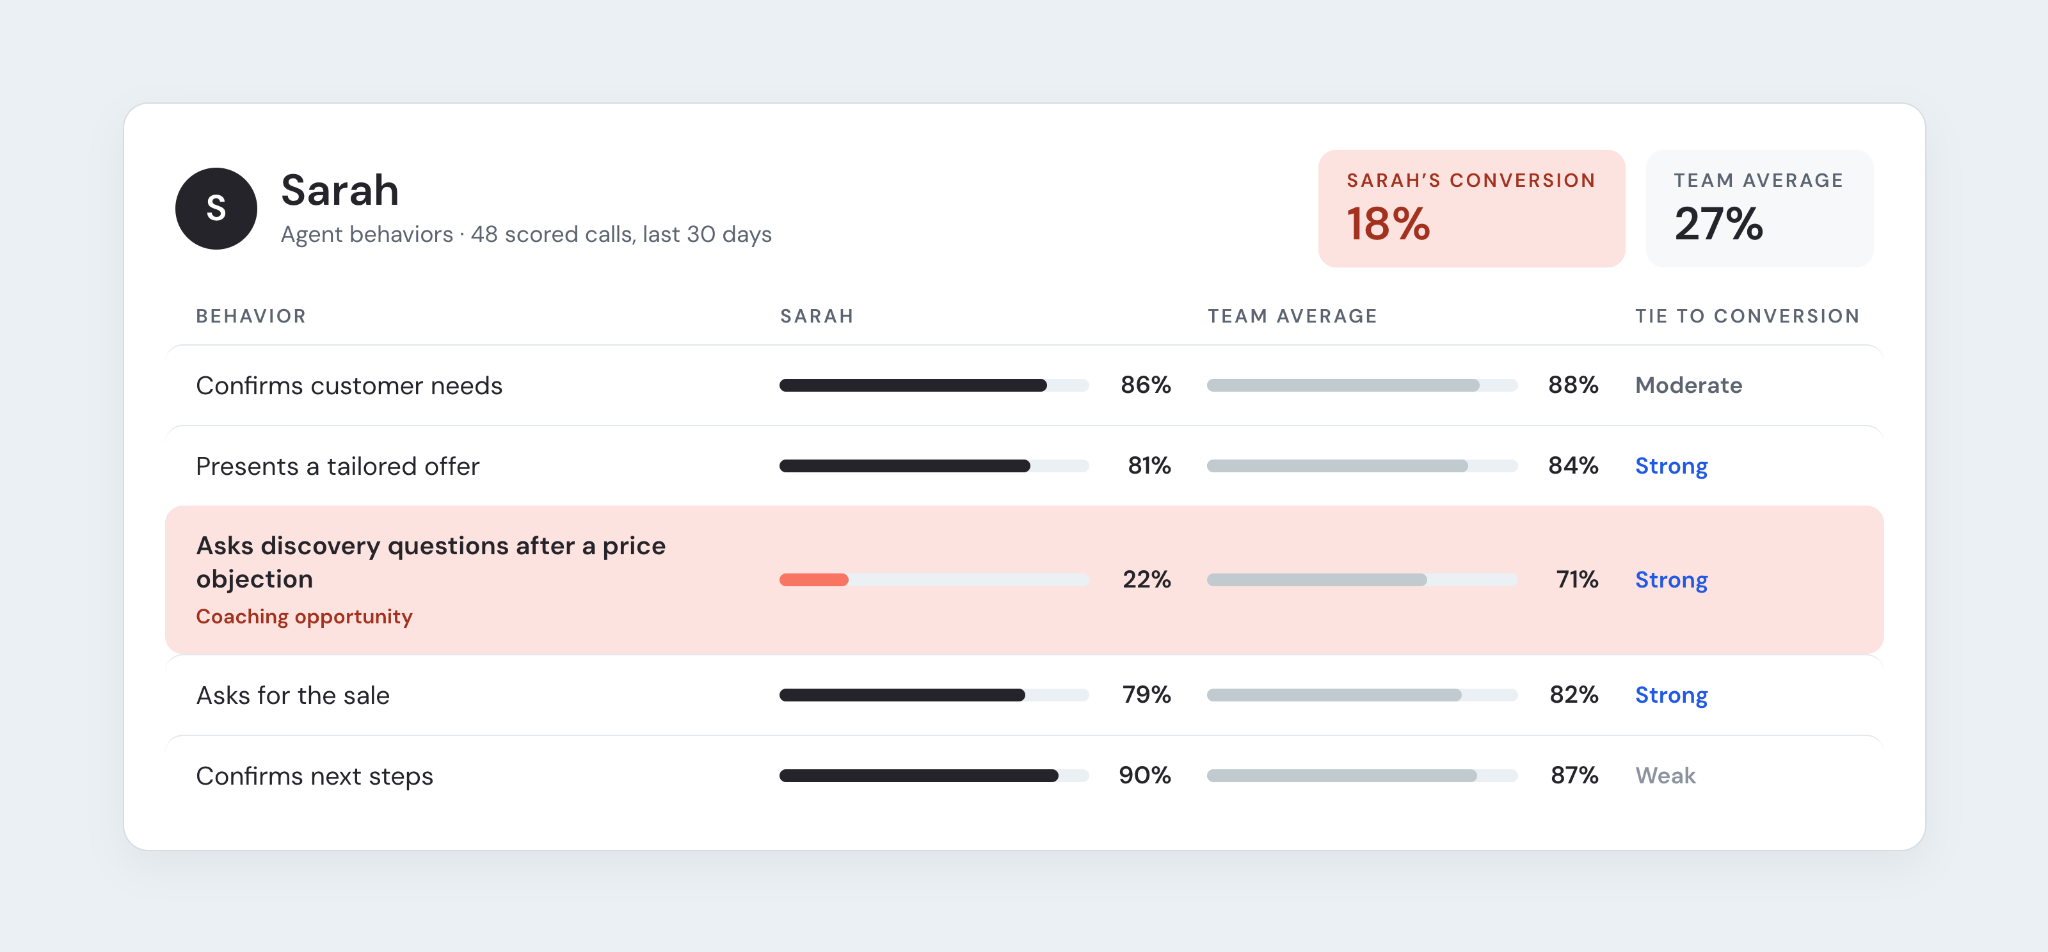
Instead of reviewing random calls, you should pull up every call where Sarah got a price objection, then compare the ones where she asked discovery questions with the ones where she didn’t.
You can recognize what she does well, show her what it looks like in her own calls, and point to the misses, all tied to an outcome she cares about.
6. Decide when to monitor calls
The steps above apply whether you score a call as it happens or afterward.
But each approach solves a different problem, and the strongest programs use both.
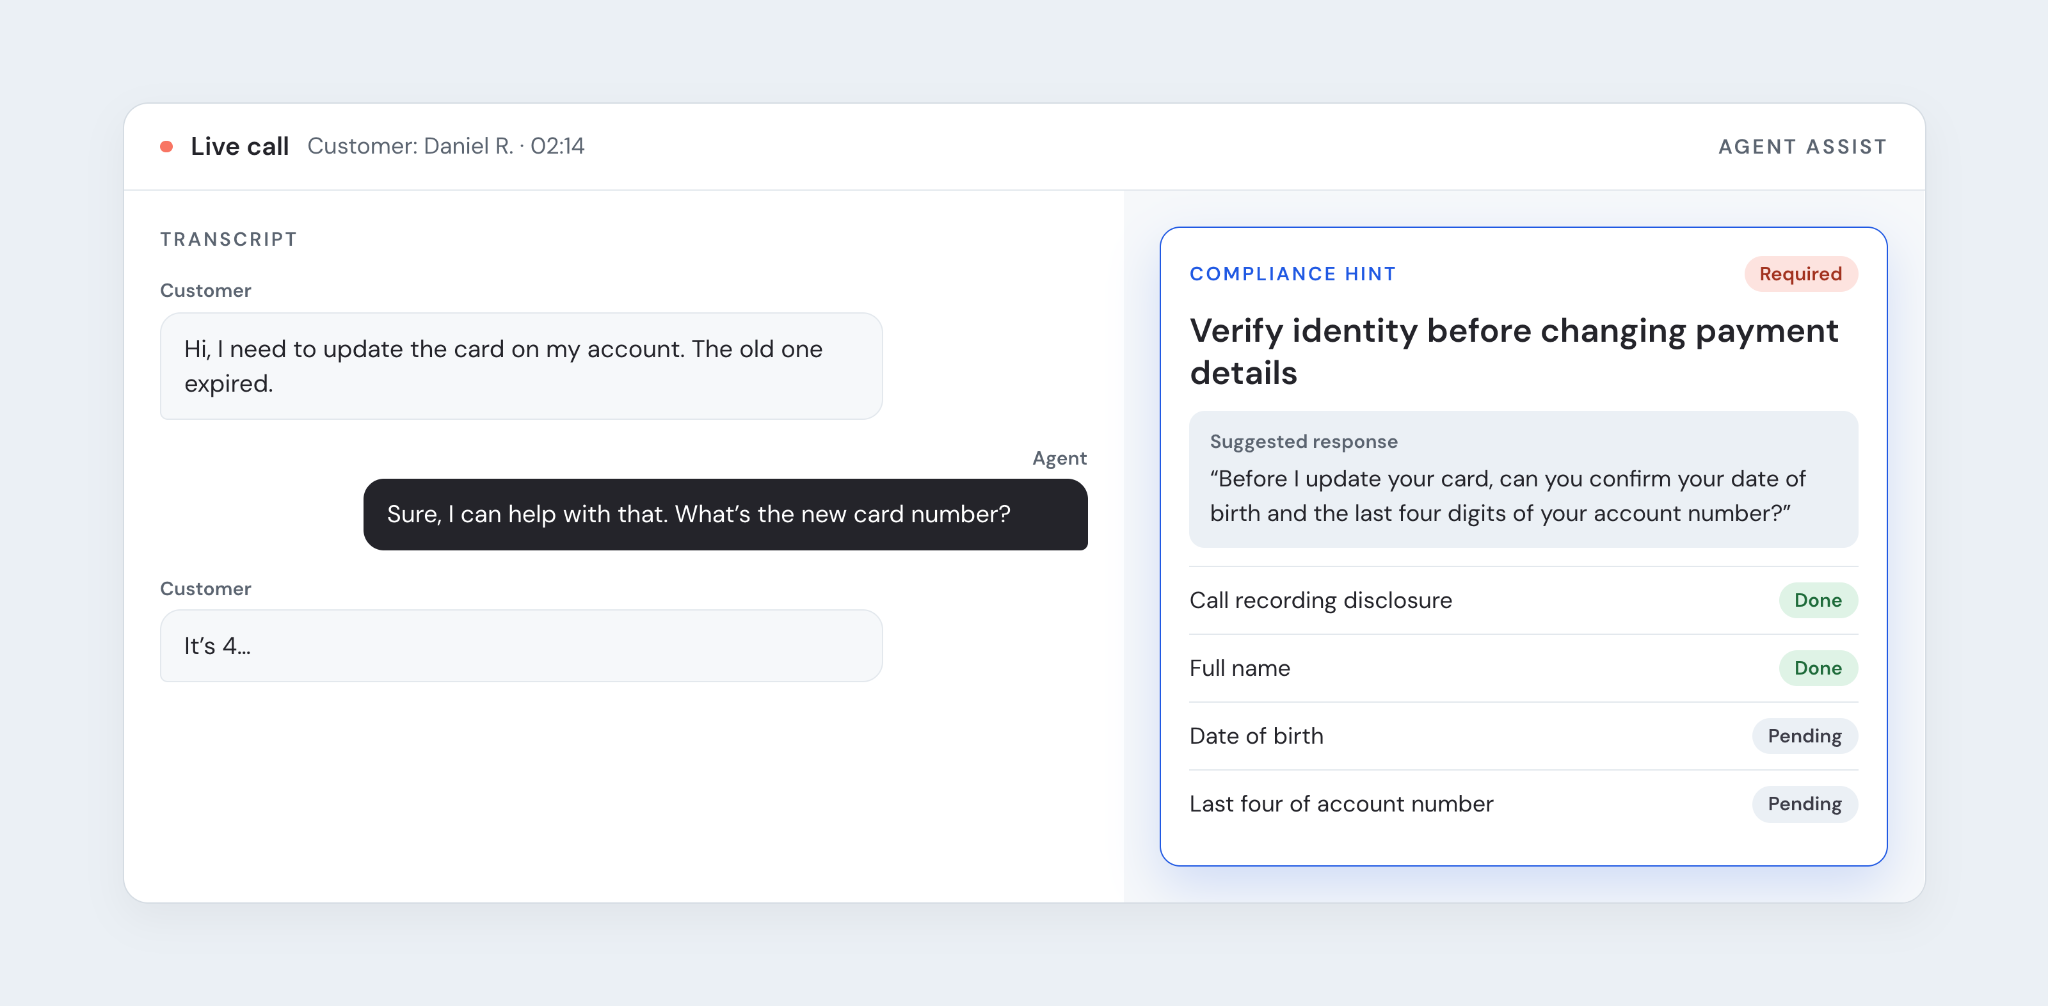
Real-time monitoring scores interactions as they happen, using conversation context, sentiment, and compliance needs to flag issues immediately. The goal is to prevent errors before they occur and resolve issues on the first contact.
It works best for:
- Compliance-critical interactions, where an immediate prompt prevents a costly violation
- High-stakes situations, where a supervisor can step in before an escalation
- New agents who need support in the moment
Post-call monitoring reveals patterns, trends, and strengths and weaknesses over time. It feeds the coaching in Step 5 and the root cause analysis for recurring issues.
7. Measure and iterate on your QM program
Once the program is running, check whether it works, and adjust as needed.
Start by measuring results. Correlate QM scores with customer satisfaction and outcome metrics, and track how quickly performance improves after coaching.
Also, track your coaches by plotting coaching activity against coaching effectiveness, so you can see who needs to coach more often or differently.
Then act on what you find:
- If many agents miss the same behavior, look for a root cause such as training, process design, system limitations, or environmental factors. Coaching individual agents on a problem caused by a broken process doesn’t fix it
- Revisit which behaviors correlate with outcomes, and focus coaching on the ones with the most impact
- Refine the scorecard when scoring patterns are inconsistent, business objectives shift, or agent feedback shows gaps between scorecard items and real service requirements
Finally, run a formal review at least every six months, with agents involved, so the criteria reflect how the work actually happens.
Related: How to scale quality management across every conversation
Run call quality monitoring on every conversation with Cresta
Every step above depends on scoring, analyzing, and coaching from the same conversation data.
Cresta, the AI operating system for CX, is built around outcome inference.
It reads each transcript to infer whether a sale was made, whether the issue was resolved, and what CSAT would be. That shows you which agent behaviors lead to more sales, faster resolutions, and higher customer satisfaction across every conversation, so your scorecards reflect what works instead of what executives assume.
Forrester’s evaluation reflects this strength. It named Cresta a Leader in The Forrester Wave™: Conversation Intelligence Solutions For Contact Centers, Q2 2025, with the highest score in the Current Offering category and the highest possible scores in 16 criteria, including Outcome Analysis and Real-Time Guidance.
With Cresta, you can:
- Analyze every interaction with Conversation Intelligence to find the behaviors that drive results
- Score 100% of conversations with Quality Management, including calibration and appeals workflows
- Turn those findings into evidence-backed coaching for each agent with Coach
- Guide agents in real time during live calls with Agentic Assist
- Handle customer conversations on their own with AI Agent, monitored by the same QM and coaching tools
- Take on the operational work behind those conversations, such as refunds, with Deputy Agent
Request a demo to see how Cresta scores, analyzes, and coaches from every conversation.